
A greenfield data-engineering engagement — three production pipelines, three data sources, four AWS regions, one unified warehouse, and a clean handover.
About Scrut Automation
Scrut Automation is an AI-powered Governance, Risk, and Compliance (GRC) platform that helps modern, cloud-native companies achieve and maintain security compliance without drowning in manual work. Instead of running audits out of spreadsheets and one-off consultant engagements, teams use Scrut to automate evidence collection, continuously monitor their controls, and manage multiple audits from a single window.
The platform maps controls across a broad set of frameworks — including SOC 2, ISO 27001, GDPR, HIPAA, and PCI DSS, among many others — so that work done once can satisfy many standards at the same time. Backed by a large library of pre-built integrations across customers' cloud and application stacks, Scrut keeps compliance continuous and audit-ready rather than a last-minute scramble. To serve a global customer base, Scrut runs production infrastructure across four AWS regions — India, the United States, Europe, and Australia.
Engagement at a glance
|
Client |
Scrut Automation — GRC & compliance automation platform |
|
Starting point |
No data pipeline. No analytics infrastructure. |
|
Pipelines built |
3 — DynamoDB, Postgres RDS, and LangSmith |
|
Sources unified |
DynamoDB (40+ tables), Postgres RDS (5 core tables), LangSmith API (AI logs) |
|
Regions |
4 — India (ap-south-1), USA (us-east-2), Europe (eu-north-1), Australia (ap-southeast-2) |
|
Daily volume |
10–50 GB across all regions |
|
Initial build |
Core platform stood up in ~6–8 weeks |
|
Warehouse modeling |
20–30 analytics-ready Redshift views |
|
Compute |
AWS Glue 4.0 — G.4X (32 DPUs) and G.2X (16 DPUs) Spark jobs |
|
Production impact |
Zero |
|
Infrastructure |
Fully serverless, AWS-native |
|
Consumption |
Metabase (BI) + Statisfy (Customer Success) |
The Challenge
Scrut Automation was growing quickly more customers, more product surface, more regions. But the faster it grew, the more it was operating on instinct. The data that should have been guiding the company's biggest decisions existed, yet none of it was reachable. Before OptiBlack, Scrut had no data pipeline and no analytics infrastructure of any kind. Every meaningful question about the business had to be answered by feel, or not at all.
Scaling globally, while flying blind
Scrut was running production across four regions and a wide product footprint, yet leadership had no dependable way to see how any of it was performing. The questions that decide where a SaaS company invests which modules customers actually adopt, where accounts are healthy or quietly slipping, how each region is trending, whether the newest features are landing — had no data-backed answer. The company was scaling faster than its ability to see itself, and that gap widens every quarter it goes unaddressed.
A business run on instinct, not evidence
Without usage and adoption data, every strategic call was being made in the dark. Product couldn't tell which features earned their place and which should be cut, so the roadmap ran on opinion. Customer Success couldn't tell which accounts were drifting toward churn until it was too late to intervene. Leadership couldn't tell which regions deserved more investment and which needed a rethink. The cost of that isn't abstract: it's slower decisions, riskier bets, and internal debates settled by whoever argues most confidently rather than by the numbers.
Data everywhere, insight nowhere
The raw material existed — but it was scattered across three very different systems (product data in DynamoDB, transactional records in Postgres, AI logs behind LangSmith) and split again across four regions. Nothing was joined, so there was no single version of the truth. Even when someone managed to pull a figure, a different export could contradict it, and no one could say which was right. And because these were live operational systems, simply querying them for answers risked slowing the very product customers were paying for — so the safe option was usually to not ask at all.
Every answer required an engineer
With no analytics layer, "how are we doing on X?" wasn't a question you could answer yourself — it was a ticket. An engineer would write a one-off query against production, and hours or days later return a number that was often already stale. Analytics wasn't self-serve; it was a recurring tax on engineering time and a hard ceiling on how fast the business could learn. The people who needed answers and the people who could produce them were never the same people.
New AI features, no way to know if they worked
Scrut was shipping AI-assisted compliance capabilities, but the conversation logs that would show whether those features were accurate, helpful, and improving sat locked behind the LangSmith API. In a compliance product, an AI that is confidently wrong isn't a cosmetic bug — it's a trust and risk problem. Yet there was no way to measure conversation quality, catch recurring error patterns, or understand cost-per-conversation. The company was shipping into a blind spot in the part of the product that most needed watching.
The stakes: a trust business has to run tight
Scrut's entire value proposition is helping other companies prove they are in control and worthy of trust. Running its own operations on guesswork sat uneasily against that promise. To keep scaling — and to keep earning the confidence of security-conscious customers — Scrut needed the same visibility and rigor internally that its platform gives everyone else. That meant building the whole analytics foundation, correctly, from nothing.
The Solution (Behind the Scenes)
OptiBlack designed and built a fully automated, AWS-native data platform. Rather than forcing one pattern onto three very different sources, we engineered a source-appropriate pipeline for each system, all converging into a single Redshift warehouse and a documented Metabase BI layer.
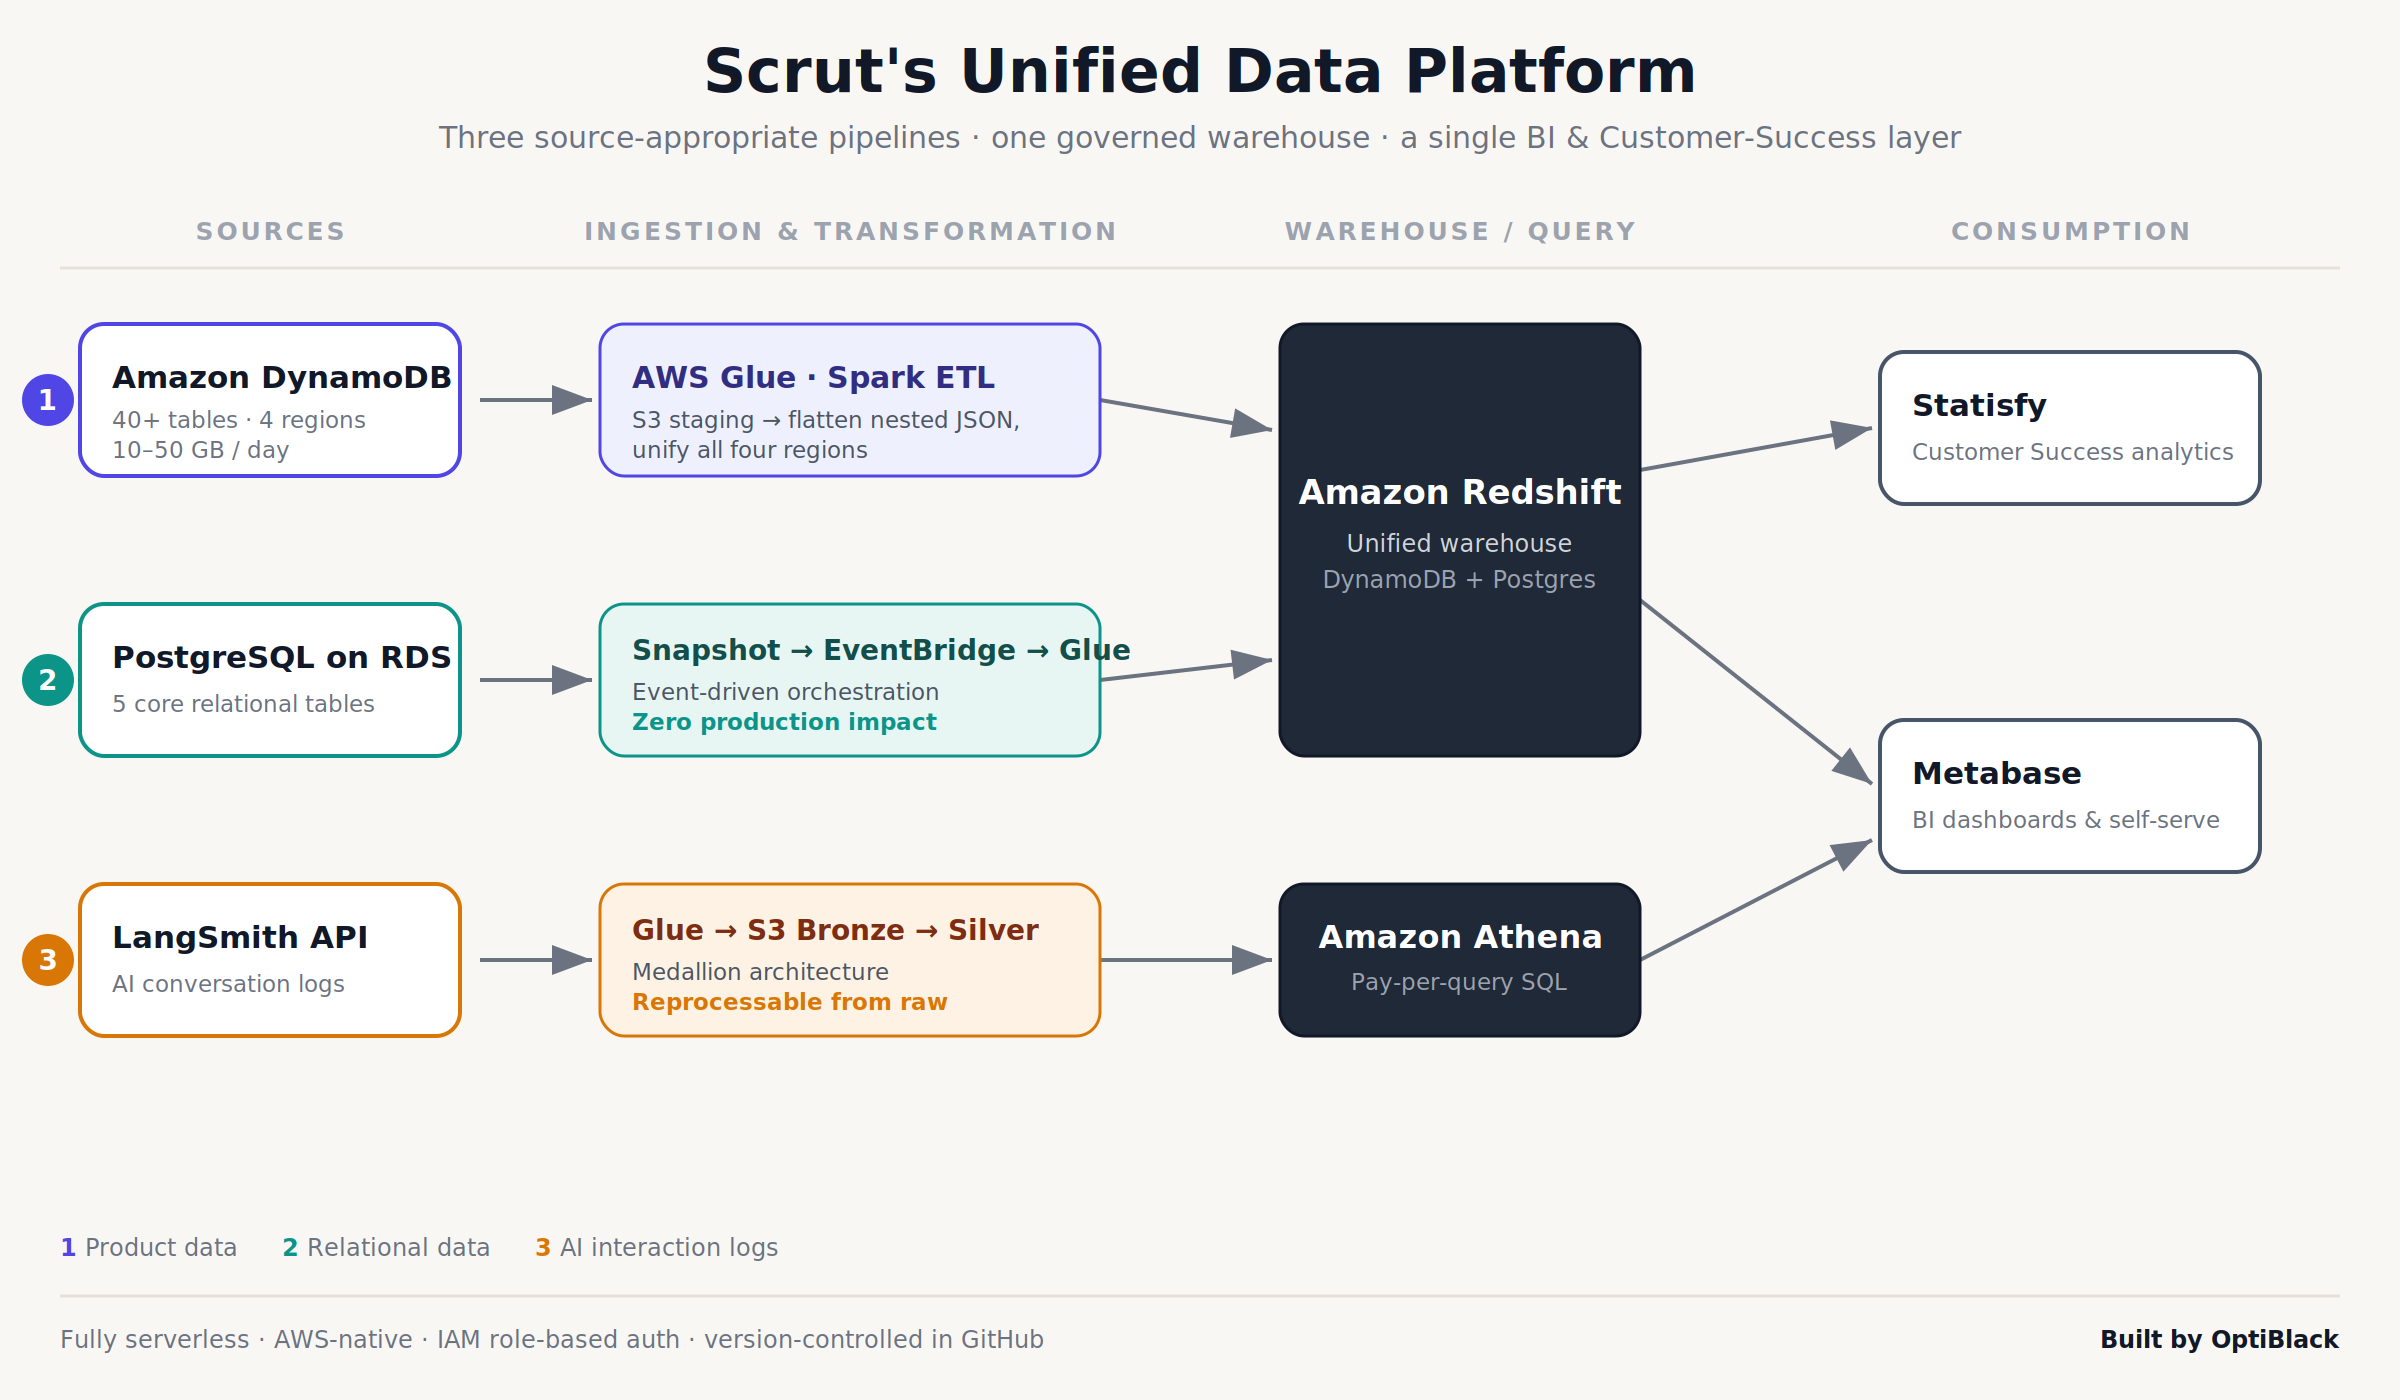
Pipeline 1 — DynamoDB → S3 → Redshift → Metabase (multi-region product data)
|
Source |
40+ DynamoDB tables across 4 regions |
|
Volume |
10–50 GB / day |
|
Compute |
AWS Glue 4.0 · G.4X workers · 32 DPUs |
|
Job shape |
34 sequential table loaders in one Spark job |
|
Warehouse output |
20–30 analytics-ready Redshift views |
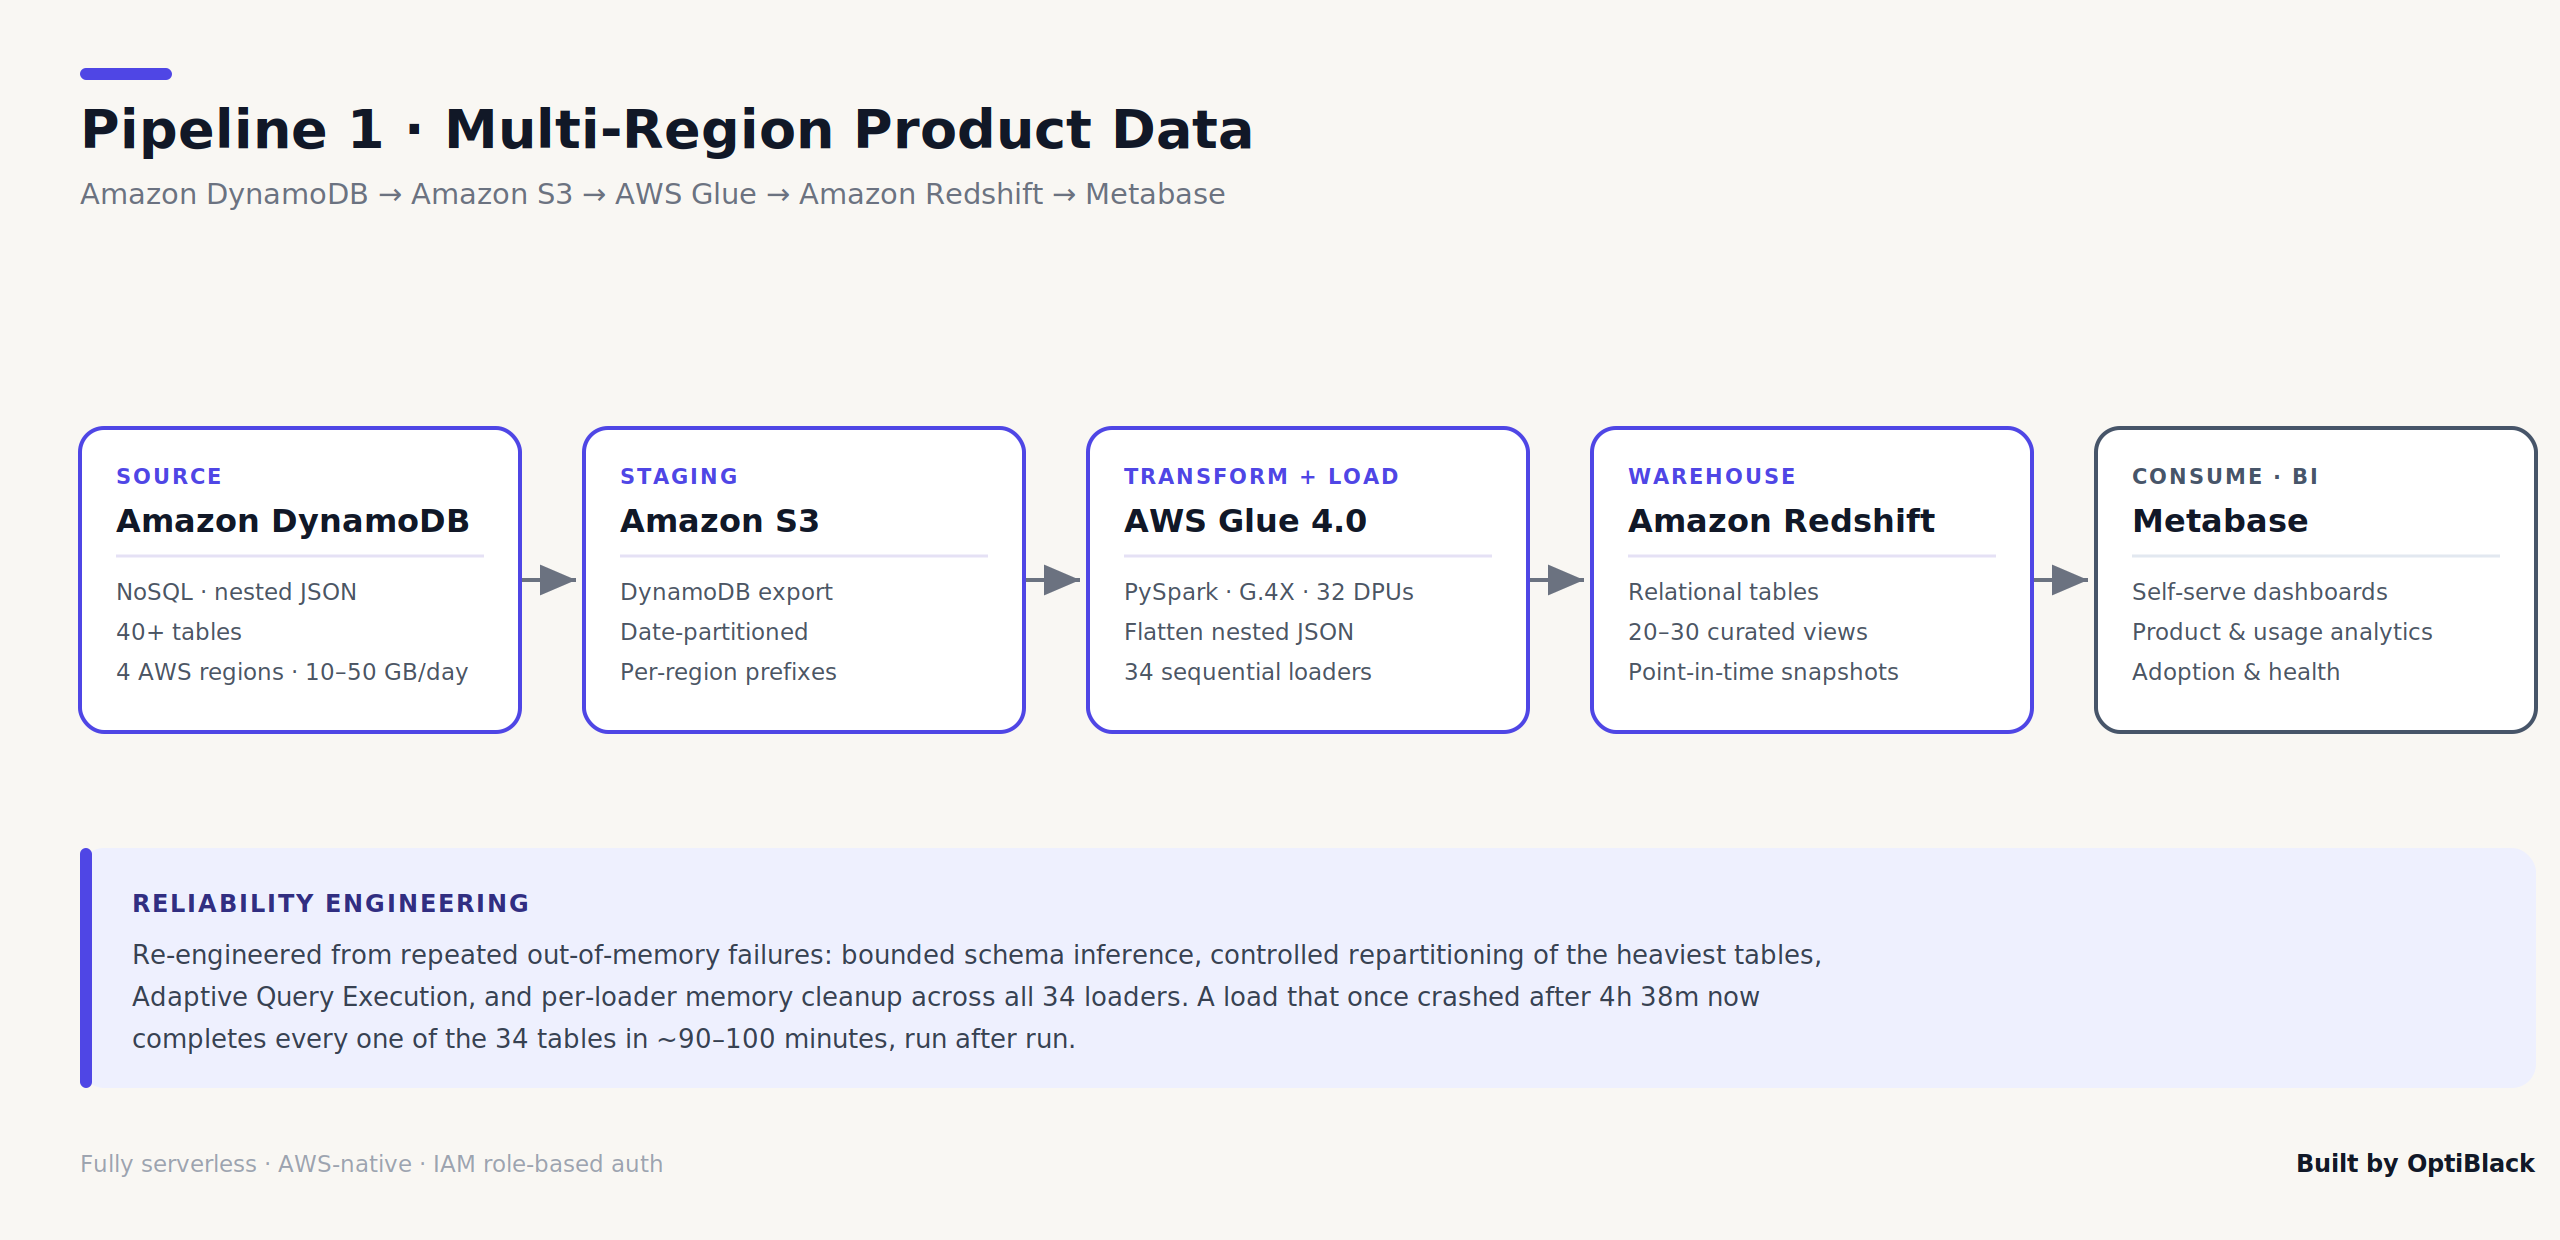
The flagship pipeline exports 40+ DynamoDB tables to S3 as date-partitioned files, then runs a PySpark job on AWS Glue that flattens the deeply nested JSON — audit logs, control mappings, risk assessments — into clean relational tables in Amazon Redshift. On top of those, Optiblack modeled 20 to 30 curated views so analysts query business concepts, not raw dumps.
Two hard problems shaped the design. First, unifying four regional silos into one global schema so leadership sees the whole business, not four fragments. Second, the fact that DynamoDB holds only current state — so the pipeline introduced point-in-time snapshots, giving Scrut the ability to track module adoption, customer health, and usage over time for the first time, instead of only seeing "right now."
Engineering it to run reliably at scale. Moving tens of gigabytes a day through 34 sequential loaders inside a single Spark job is exactly where naïve pipelines fall over — and early runs did. The heaviest tables exhausted executor and driver heap, and one early production run crashed after 4 hours 38 minutes with a driver out-of-memory error. OptiBlack re-engineered the job from the memory model up: bounded schema inference (which cut the gap between loaders from 10–15 minutes to roughly 10 seconds), explicit repartitioning of the heaviest tables, Adaptive Query Execution with tuned shuffle partitions, disciplined memory cleanup after each of the 34 loaders, and an executor idle-timeout so Spark stopped killing workers between tables. The result: a job that once died after 4h 38m now loads all 34 tables end-to-end in ~90–100 minutes, run after run, with no OOM failures.
Pipeline 2 — Postgres RDS → Snapshot → EventBridge → Glue → Redshift → Statisfy + Metabase (zero-impact relational data)
|
Source |
5 core tables across 2 production databases, 4 regions |
|
Extraction |
Automated RDS snapshot export (storage-layer, not query-based) |
|
Orchestration |
EventBridge — event-driven |
|
Compute |
AWS Glue 4.0 · G.2X workers · 16 DPUs |
|
Cadence |
Weekly today, architected to move to daily |
|
Production impact |
Zero |
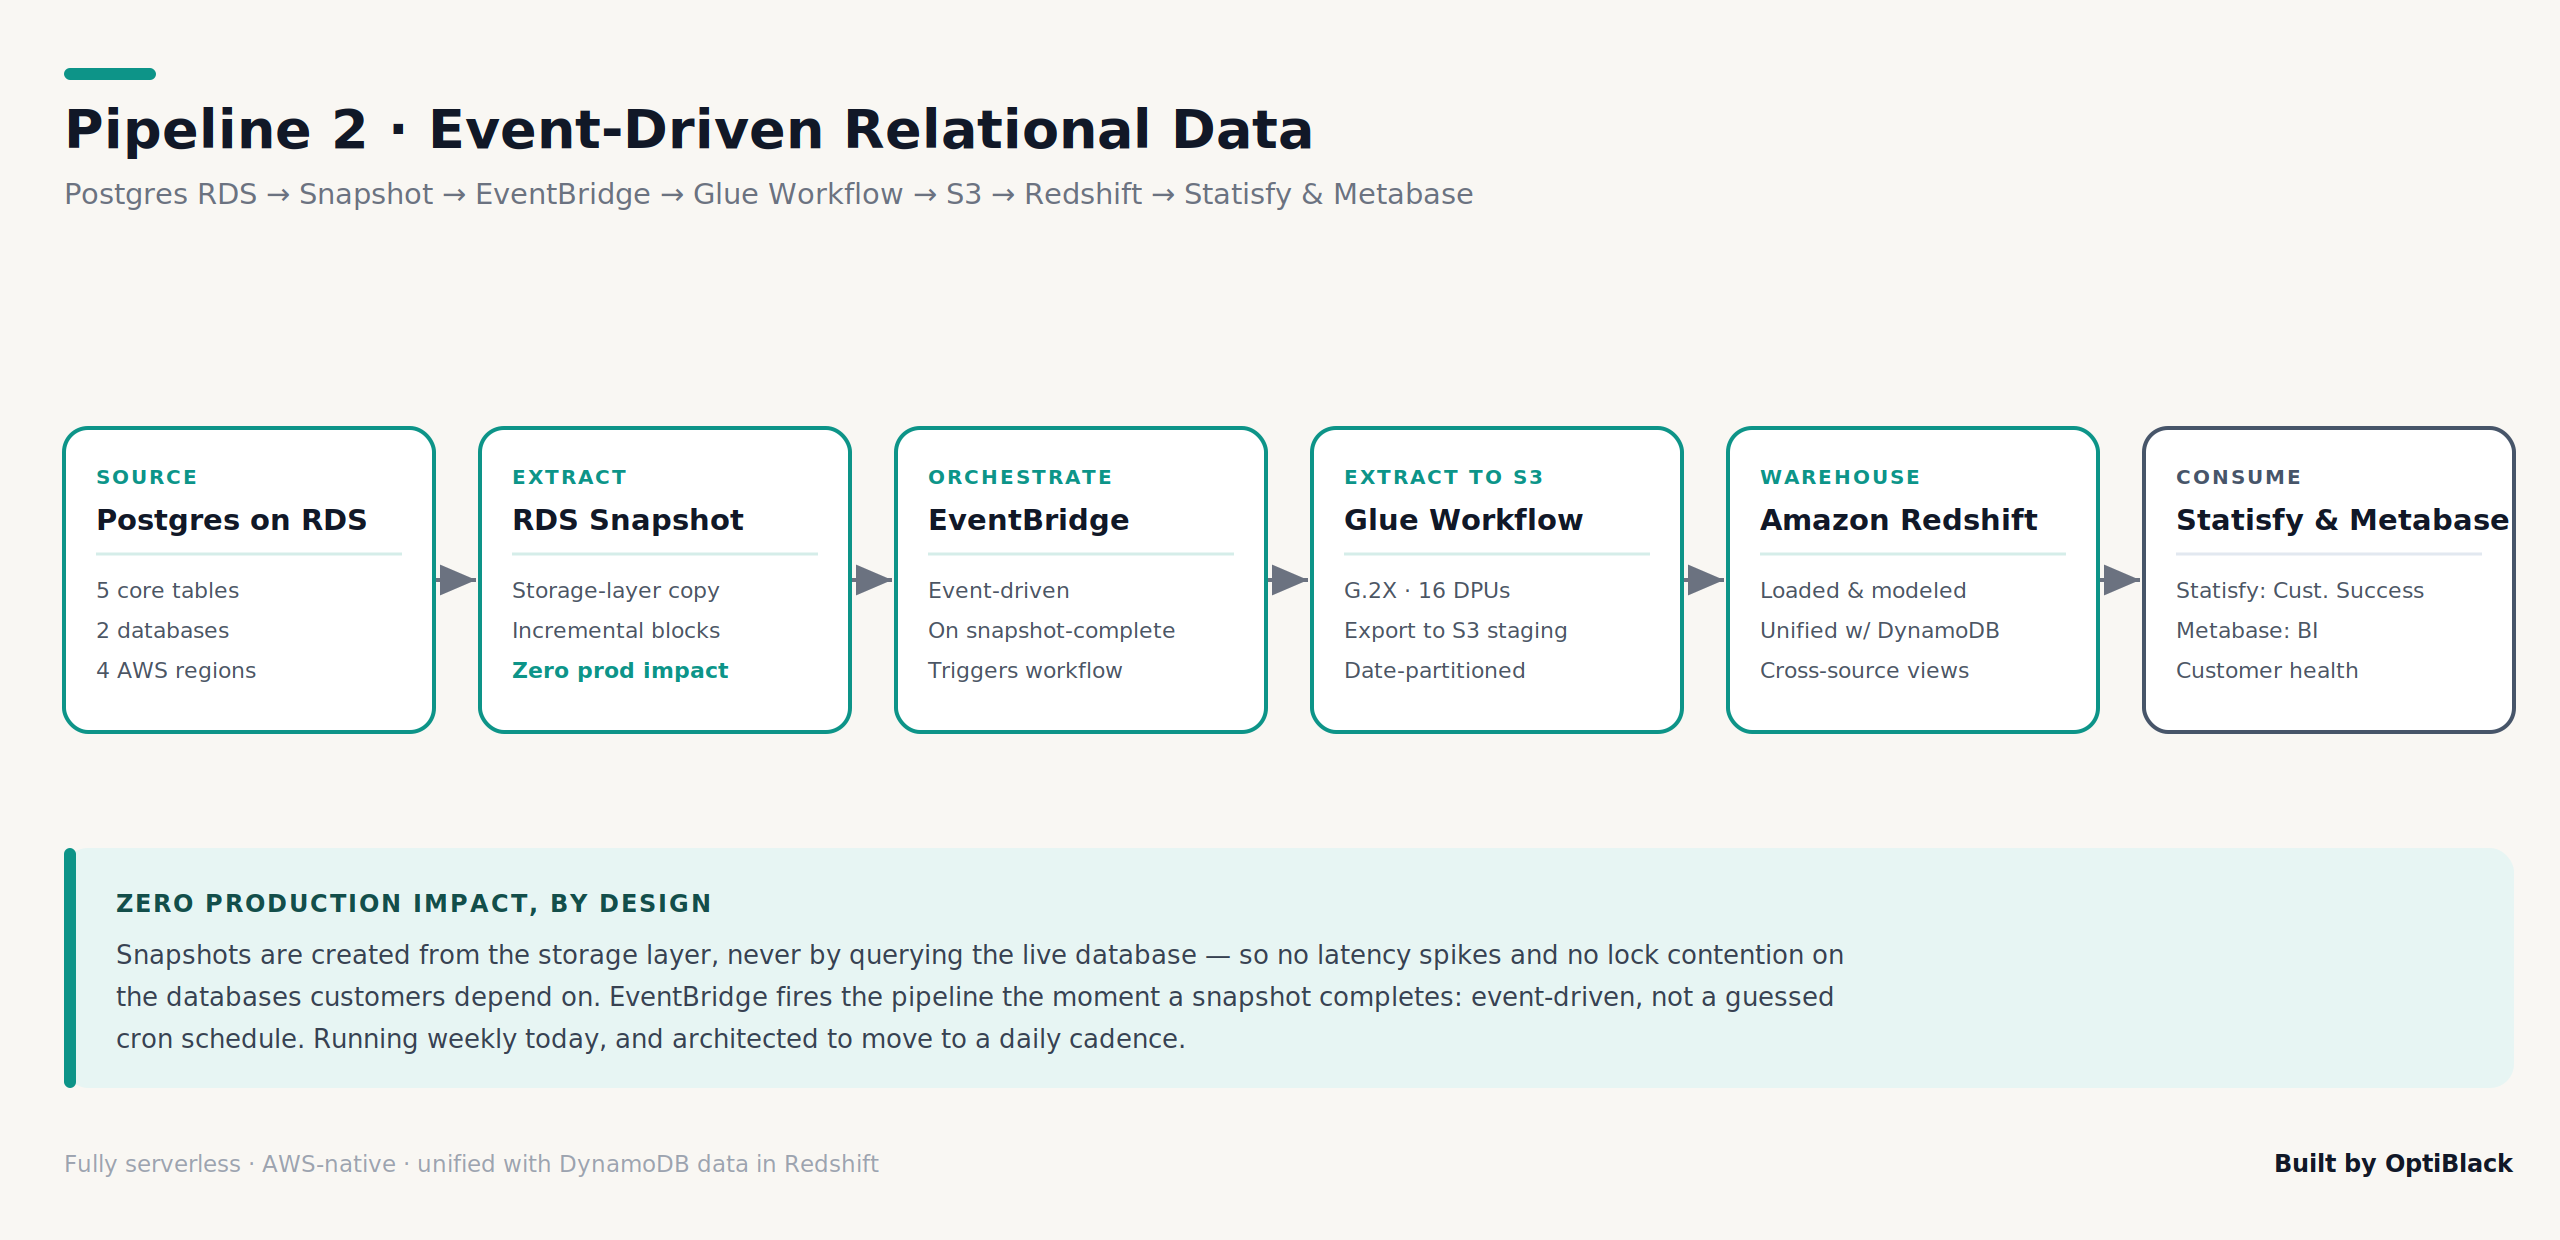
Postgres required a completely different approach, because running analytical extraction against a live production database would compete with customer-facing traffic. The design decisions here are the ones a CTO will recognize as the right ones:
- Snapshots instead of read replicas or CDC. Extraction runs against automated RDS snapshots point-in-time copies AWS creates from the storage layer, not by querying the live database so there is zero production impact: no lock contention, no latency spikes. Snapshots are incremental (only changed blocks are stored), making this dramatically cheaper than an always-on read replica or standing up CDC for what is, in practice, a daily batch requirement. Every snapshot also captures all five tables at a single consistent point in time, which preserves the foreign-key integrity that relational data depends on.
- EventBridge instead of cron. Rather than guessing a schedule and hoping the snapshot had finished, the pipeline is event-driven, EventBridge listens for the snapshot-completion event and only then triggers the Glue workflow. It runs exactly when the data is ready, never before. The Glue job (G.2X, 16 DPUs) reads the exported data from a date-partitioned, per-region S3 staging layer and loads it to Redshift.
- Dual consumption, unified storage. This relational data feeds two destinations Statisfy for customer-success analytics and Metabase for broader BI, while landing in the same Redshift warehouse as the DynamoDB data, so the two sources can be joined for genuinely cross-source analytics. The pipeline currently runs weekly and was architected to shift to a daily cadence once the source databases are snapshot-split.
Pipeline 3 — LangSmith API → Glue → S3 (Bronze → Silver) → Athena (AI conversation logs)
|
Source |
LangSmith API — LLM logs, agent traces, prompt/response, feedback |
|
Bronze layer |
Amazon S3 · raw JSON · date-partitioned · immutable |
|
Silver layer |
Amazon S3 · Parquet · columnar · schema-enforced |
|
Query engine |
Amazon Athena · serverless · pay-per-query |
|
Pattern |
Medallion (Bronze → Silver) |
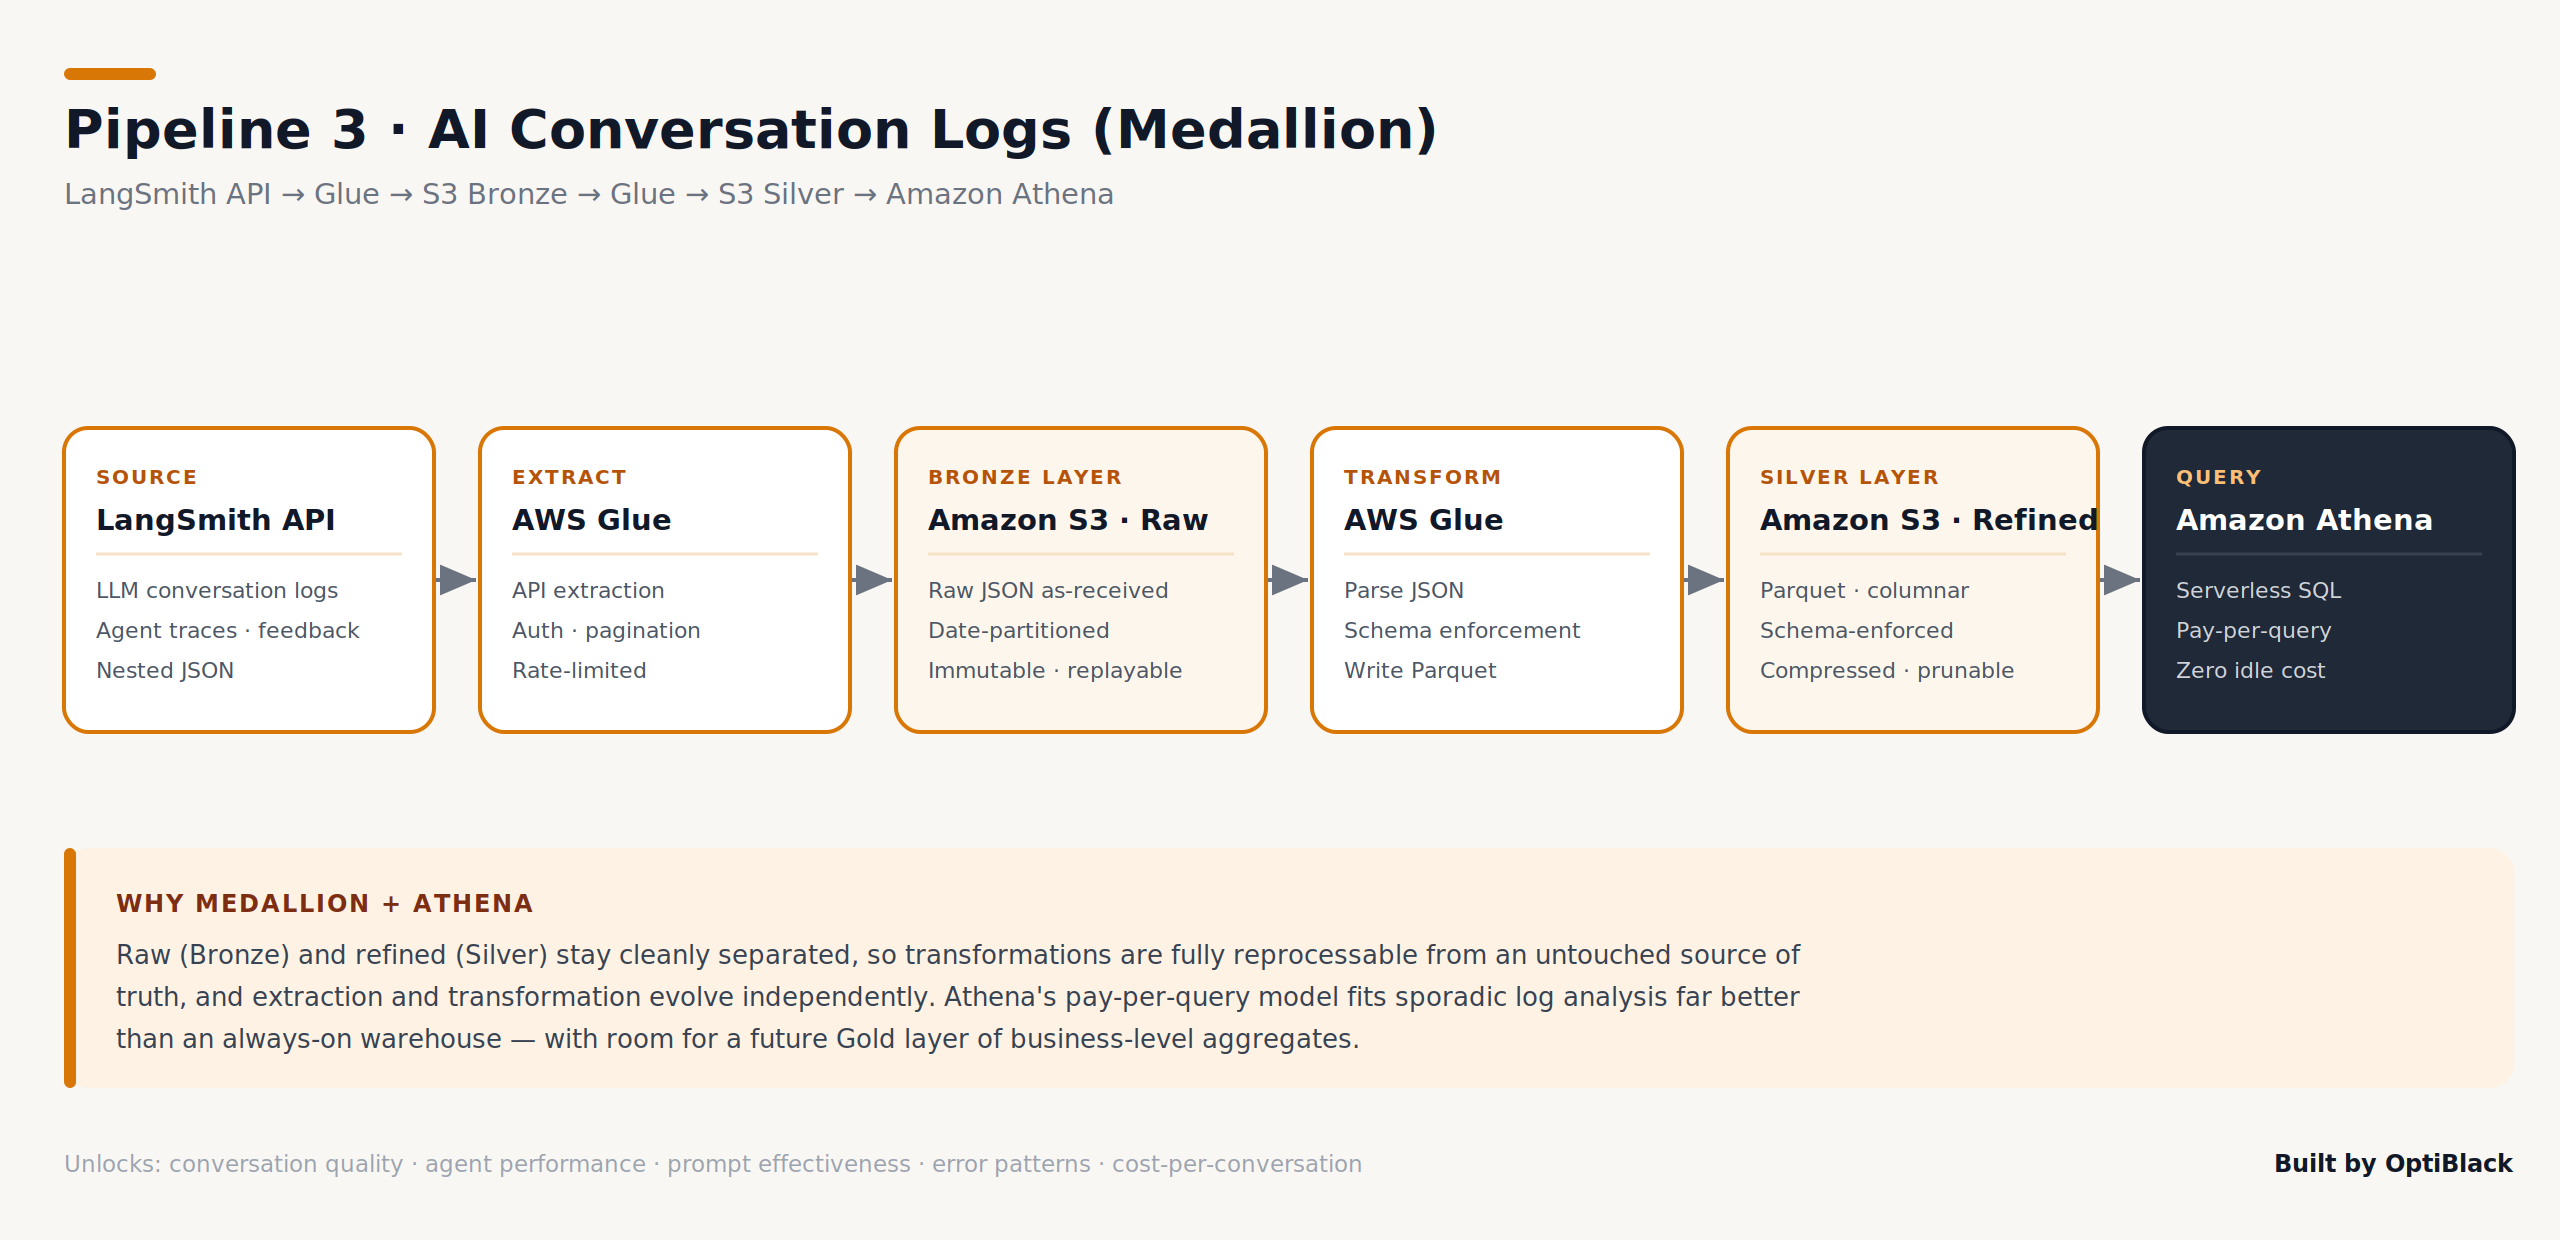
Scrut's AI-assistant interaction logs, conversation traces, agent runs, prompt/response pairs, and feedback, called for a third pattern. Here OptiBlack implemented a medallion architecture: a Glue job connects to the LangSmith API (handling authentication, pagination, and rate limiting) and lands the raw responses in an immutable, date-partitioned Bronze layer in S3; a second Glue job parses the JSON, enforces a schema, and writes Silver as columnar Parquet; and Amazon Athena queries the Silver layer directly in S3 with standard SQL.
Two deliberate choices drove the design. Athena over Redshift: for a log-analysis workload that's queried sporadically rather than powering always-on dashboards, a pay-per-query model with zero idle cost is dramatically cheaper than an always-on warehouse. The medallion pattern: keeping raw and refined data cleanly separated makes transformations fully reprocessable, if the parsing logic changes, Silver rebuilds from an untouched Bronze source of truth, and decouples the two jobs, so an API change only touches extraction while a requirements change only touches transformation. It also leaves room for a future Gold layer of business-level aggregates without re-architecting.
The unifying layer, and the operational rigor around it
Building the three pipelines was only part of the job. Turning raw data into something the business could use safely and durably took the rest: unifying DynamoDB and Postgres data in a single Redshift warehouse (the 20–30 curated views that power analytics); running and documenting Scrut's Metabase environment so analysts could self-serve; chaining jobs by event triggers rather than independent schedules so nothing runs before its data lands; authenticating everything on IAM roles with no hardcoded credentials; version-controlling the codebase in GitHub; and capturing every pipeline, upgrade, and fix in runbooks and knowledge-transfer sessions so Scrut's team could take full ownership at handover.
Business Impact
Scrut went from having no analytics capability at all to a business that can finally see itself and act on evidence. The value isn't the pipelines it's what the company can now do that it simply couldn't before.
Leadership can see the business and decide on evidence
The questions that used to have no answer now have dashboards behind them. Product usage, module adoption, customer health, and regional performance are visible in Metabase, self-serve, without waiting on an engineer. Decisions that were made on instinct are now grounded in data, which means they're faster to make and carry less risk. Meetings shift from arguing about what's happening to deciding what to do about it.
Product can prioritize on what customers actually do
With adoption data across the product surface surfaced through curated views, the product team can finally see which modules land and which are ignored. The roadmap can be steered by evidence instead of assumption — building more of what works, and cutting what doesn't, with the data to back the call.
Customer Success can get ahead of churn
Statisfy, fed by the unified relational data, gives the CS team a real view of account health — so they can spot accounts drifting toward trouble and intervene before renewal, rather than discovering the problem when it's already lost. In a business where retention and trust compound, moving from reactive to proactive is worth real revenue.
Go-to-market can double down where it works
Regional performance is now visible across all four regions. Leadership can direct GTM effort and resources toward the regions and segments that are actually winning, instead of spreading investment evenly and hoping — turning four opaque markets into four measurable ones.
One number the whole company trusts
Because product and transactional data are unified in a single Redshift warehouse, everyone works from one source of truth. The era of contradictory exports is over: cross-source questions that were previously impossible are now just queries, and the whole organization can align around the same numbers instead of debating whose spreadsheet is right.
The business can finally measure its own AI
With the LangSmith logs queryable, Scrut can see how well its AI features are actually performing — conversation quality across frameworks, agent effectiveness, recurring error patterns, adoption, and cost-per-conversation. That closes the loop on the fastest-moving, highest-stakes part of the product: the team can now improve the AI with evidence and catch problems early, rather than shipping into a blind spot.
Answers in minutes, not an engineering ticket
Analytics is now self-serve, which quietly removes a recurring drain on the business. Engineers are no longer pulled off product work to write one-off queries against production, and everyone else gets answers in minutes instead of days. The people who need the data and the people who can get it are, at last, the same people.
History, so the company can tell what actually worked
Point-in-time snapshots mean Scrut can see how any metric moves over time. The team can now tell whether a product change, a pricing move, or a GTM push genuinely shifted the needle — measuring cause and effect instead of staring at a single snapshot of "now."
A capability Scrut owns, and can build on
None of this was left as a black box. Documented, transferred through structured knowledge transfer, and handed over cleanly, the platform is run by Scrut's own engineers and it's built to grow, with room for new data sources and higher-level aggregates as the business's questions get more ambitious. The value keeps compounding long after the engagement closed. What Scrut got wasn't a report; it was a permanent capability.

